
Events
Live from Luma
Boundaries traced from Survey of India maps by DataMeet (CC BY 4.0). Not to scale.
Community
Events and speaker sessions
Live talks, reading groups and city meetups, all on our Luma calendar.
What’s on
Past
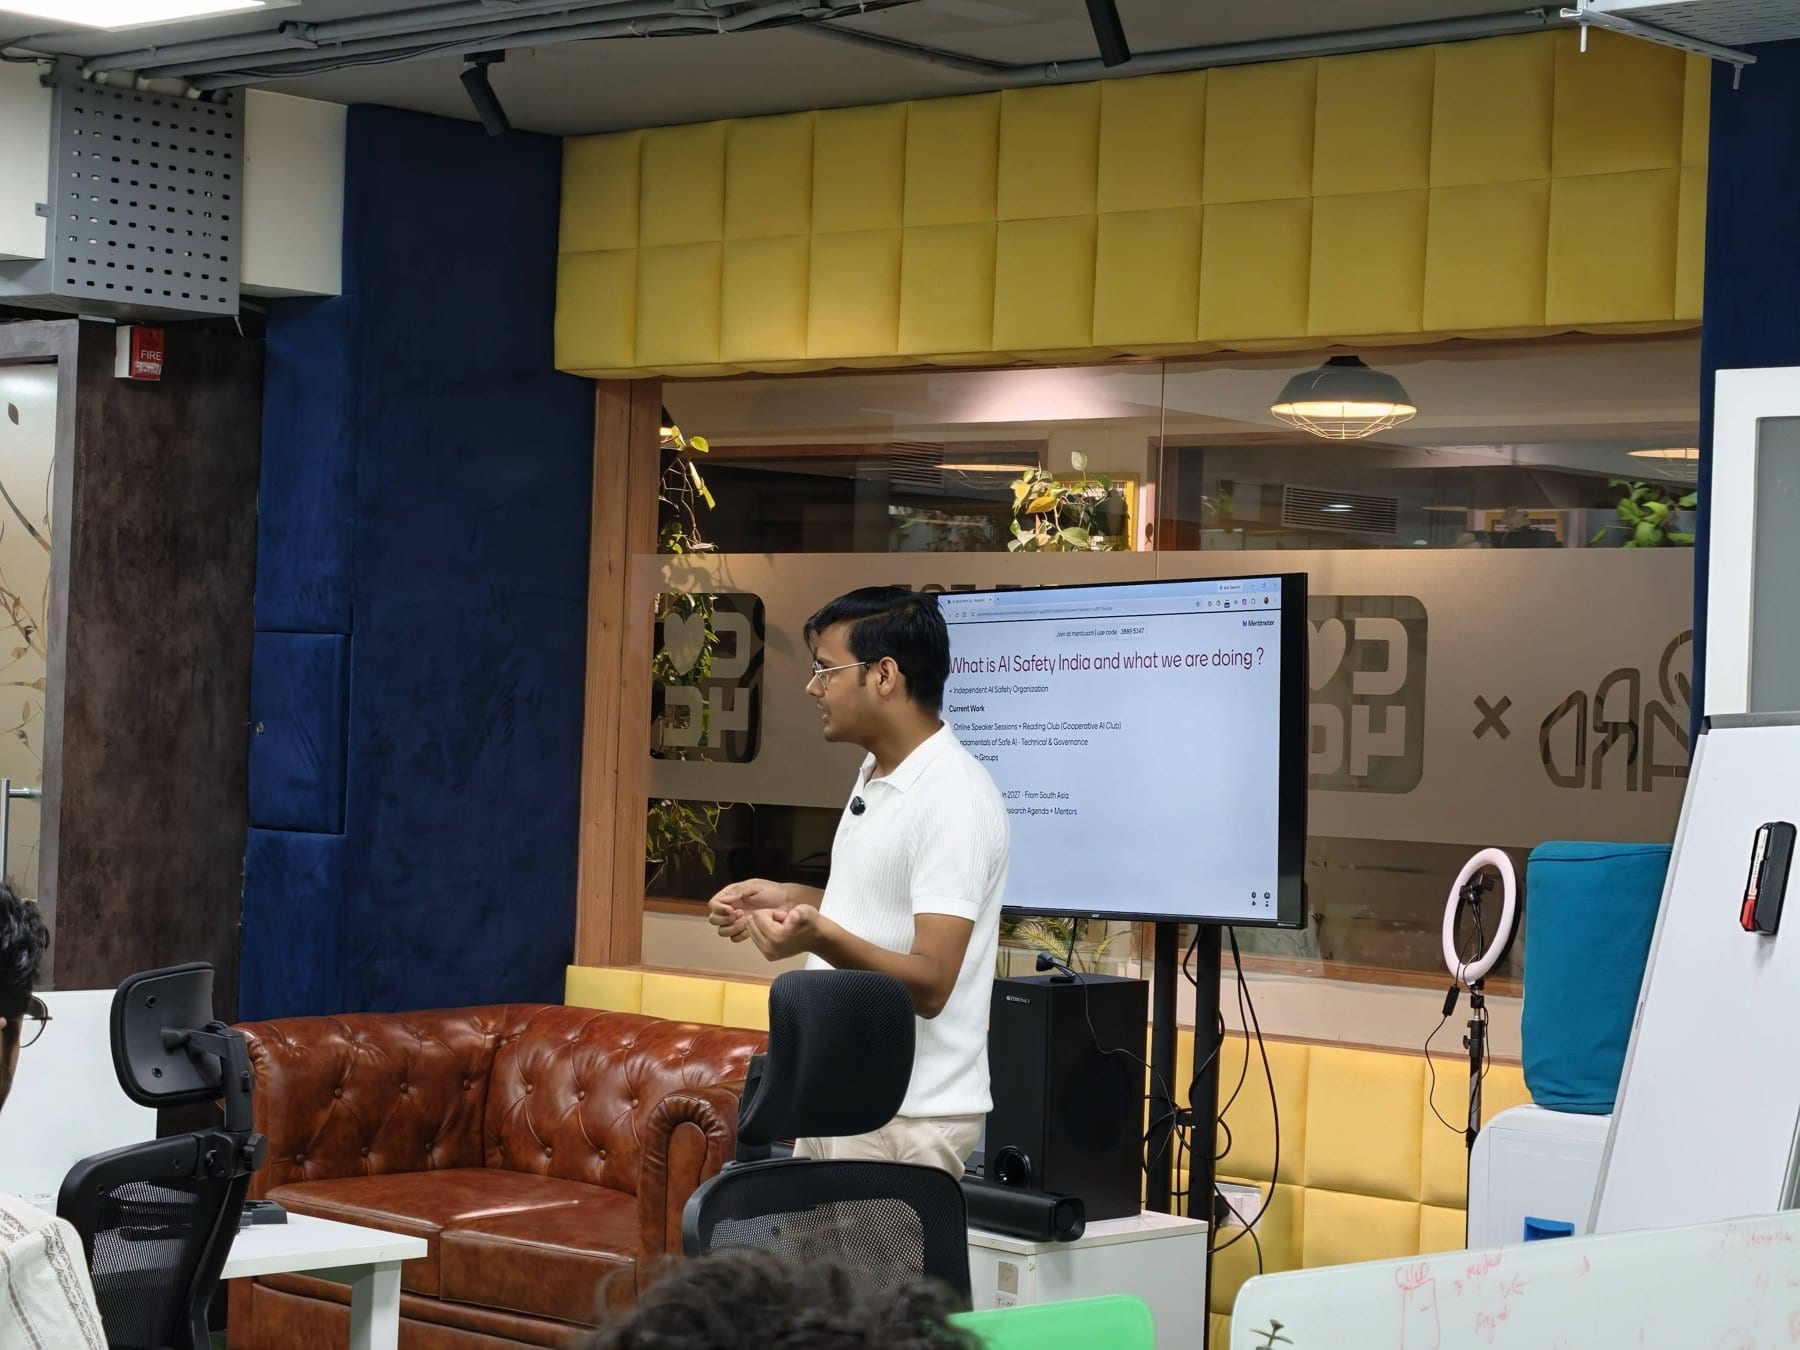
- Sat, 17 Oct 2026May the Models Be Ever in Your FavorBengaluru
- Sun, 20 Sept 2026AI Safety India Meet UpNew Delhi
- Sat, 12 Sept 2026AI Safety Meet UpBengaluru
- Sun, 6 Sept 2026Cameras, Consent & AI: What Should Be Allowed?Online
- Tue, 1 Sept 2026AI Safety CoworkingOnline
- Sat, 8 Aug 2026Find your way in AI SafetyOnline
- Fri, 24 Jul 2026Hackathon Winners Present: Do Multilingual Vision-Language Models Abstain under Cross-Modal Conflict in Low-Resource Languages?Online
- Sun, 24 May 2026India AI Impact Summit 2026 - What Actually Happened and What's Next for AI SafetyOnline
Nothing planned yet.
Subscribe on Luma and the next one reaches you first.
From the room
Write-ups
All posts on SubstackDo multilingual vision-language models abstain under cross-modal conflict in low-resource languages?
Anvesh Reddy Lankala, Vicky Feliren and Akansh Jain, winners of the Apart Research Global South AI Safety Hackathon (Asia-Pacific track)
What they found
- VLMs get about twice as text-biased in Hindi and Telugu as in English.
- High abstention can be a mask: Qwen followed the text 81% of the time when it failed to use the image.
- Steering vectors trained on English transfer for abstention models, but fail for heavily text-biased ones.